sayFUSE S3 Object Storage
Scalable Object Storage for Backup, Archiving, Data Lakes and Data-Intensive Applications
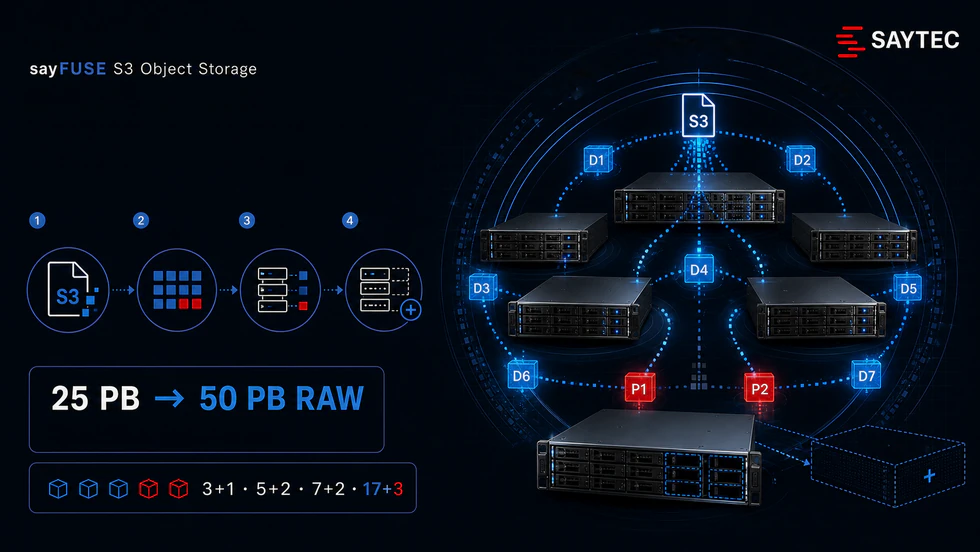
A storage system that grows with your data – without changing the architecture, without new storage silos and without disruptive migration.
sayFUSE S3 Object Storage is a horizontally scalable S3 platform for large and continuously growing datasets. Capacity and overall performance can be expanded step by step: first by adding drives to existing nodes, then by adding further nodes to the cluster.
- Grow instead of migrating. Expand existing infrastructure as needed and protect investments for the long term.
- Scale capacity and performance together. Every additional node brings drives, CPU, I/O and network resources – and therefore additional performance – into the cluster.
- Unified S3 architecture. Run active data, backup and archiving on the appropriate storage tiers.
- Integrate automatically. Authorised nodes adopt the cluster configuration and take part in data distribution, redundancy and processing.
Designed for
Backup & long-term archiving
Scalable S3 target storage for growing backup volumes.
Enterprises & public authorities
Central object storage for demanding operating models.
Data lakes & analytics
Parallel data paths for data-intensive analysis.
KRITIS-adjacent environments
Resilient architecture with configurable redundancy.
Architecture & scaling: Growth within the same platform
The scale-out principle combines linear expandability with a consistent operating model.
Two ways to expand
1. In-node scaling
Free drive bays are fitted with additional storage media. Ideal when the main requirement is more capacity.
2. Cluster scaling
Additional nodes increase capacity and provide extra CPU, I/O and network performance.
Simply connect, join automatically
Once the authorised system key has been entered, a new node connects to the existing cluster, adopts the required configuration and is integrated into storage, data distribution, redundancy and processing. No separate storage silo or reinstallation of the entire platform is required.
Why performance grows too
- Distributed data paths: objects are processed in parallel across multiple nodes, drives and network paths.
- More resources with every expansion: each node adds to the available storage media, CPU, I/O and network capacity.
- No central scaling bottleneck: total throughput can grow with the size of the cluster – depending on object sizes, storage media, network, redundancy scheme and workload.